A robot can observe an operator moving towards an object without knowing why that object matters. This extended abstract proposes adding vision-language reasoning to GUIDER so that a mission expressed in ordinary language can influence the robot’s interpretation of motion and scene geometry.
The Missing Context in Geometric Intent
An object may be close, visible and reachable but irrelevant to the task. A request such as bringing a drink makes a mug more relevant than a nearby book, even before the arm moves decisively towards either one. Geometry alone cannot supply that relationship between an object and the mission.
The proposed extension uses semantic relevance as a prior: an initial preference over candidate objects that subsequent movement evidence can support or overturn. This is not a replacement for perception or tracking. A language model cannot make a missing object physically present, and a plausible description does not establish a reachable grasp.
How the Proposed Pipeline Fits Together
Perception provides candidate objects and image crops. A vision-language model compares those crops with the operator’s prompt, estimating which candidates fit the mission. Optional text-only ranking of detected labels offers another route to semantic information, although a label contains less visual detail than the object crop.
The resulting relevance information feeds the probabilistic intent-estimation process. Motion remains evidence about what the operator is actually doing. Keeping both matters when the prompt is broad, several objects fit it or the person changes direction.
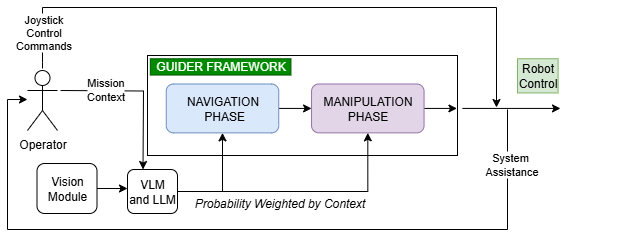
The proposal uses zero-shot image-and-text scoring rather than reporting a newly fine-tuned model. Its intended commitment policy combines a belief threshold with operator acceptance. Crossing a model threshold and receiving permission to act are separate events; confidence is not a substitute for the person’s agreement.
Why a High Score Can Still Be Misleading
Normalising several scores so they sum to one produces a convenient set of weights, but not necessarily calibrated probabilities. Calibration would require evidence that predictions with a stated confidence are correct at a corresponding frequency on relevant data.
Candidate selection also matters. If perception misses the intended object, the system can become highly confident in the wrong remaining candidate. If semantic filtering removes an object too early, a revised prompt may require restoring it rather than merely adjusting the existing weights.
These are reasons to evaluate contradictory context, ambiguous labels and prompt changes—not claims that the extended abstract already solves those cases. The semantic prior should help resolve uncertainty without making the system unable to revise its interpretation.
What the Paper Establishes
This is a proposal and planned evaluation, not a completed comparative benchmark. Integration targets an Isaac Sim mobile manipulator with a Franka Emika arm on a Ridgeback base. The work outlines context-aware assistance and adaptation when an operator changes the mission.
There are no measured task-time or accuracy improvements here to report as established benefits. Target accuracy, time to confidence and assisted completion time would answer different questions: whether the estimate is right, whether it becomes useful early and whether acting on it actually helps.
A full reproduction would require the specific models, prompts, scoring and candidate-pruning rules, scene and controller, plus the evaluation protocol. Those details cannot be filled in by assuming that any vision-language model implements the same system.
Testing and Real-World Use
This could be tested in simulation by presenting the same scene and movement with different mission prompts, then measuring whether relevant targets are identified correctly and whether revised instructions are respected. In assistive mobile manipulation, semantic context could make help more relevant to a person’s request while preserving confirmation before an inferred intention becomes an action.
Source and Status
The full extended abstract contains the proposed architecture and simulation illustration. It should be read as a research direction that complements geometric intent prediction, not as evidence of a finished autonomous deployment.